Earth Genome has added a new AI-driven feature for creating reference layers in Earth Index, a similarity-search application allowing conservationists to identify locations of environmental harm.
Andrew Milligan, Earth Genome:
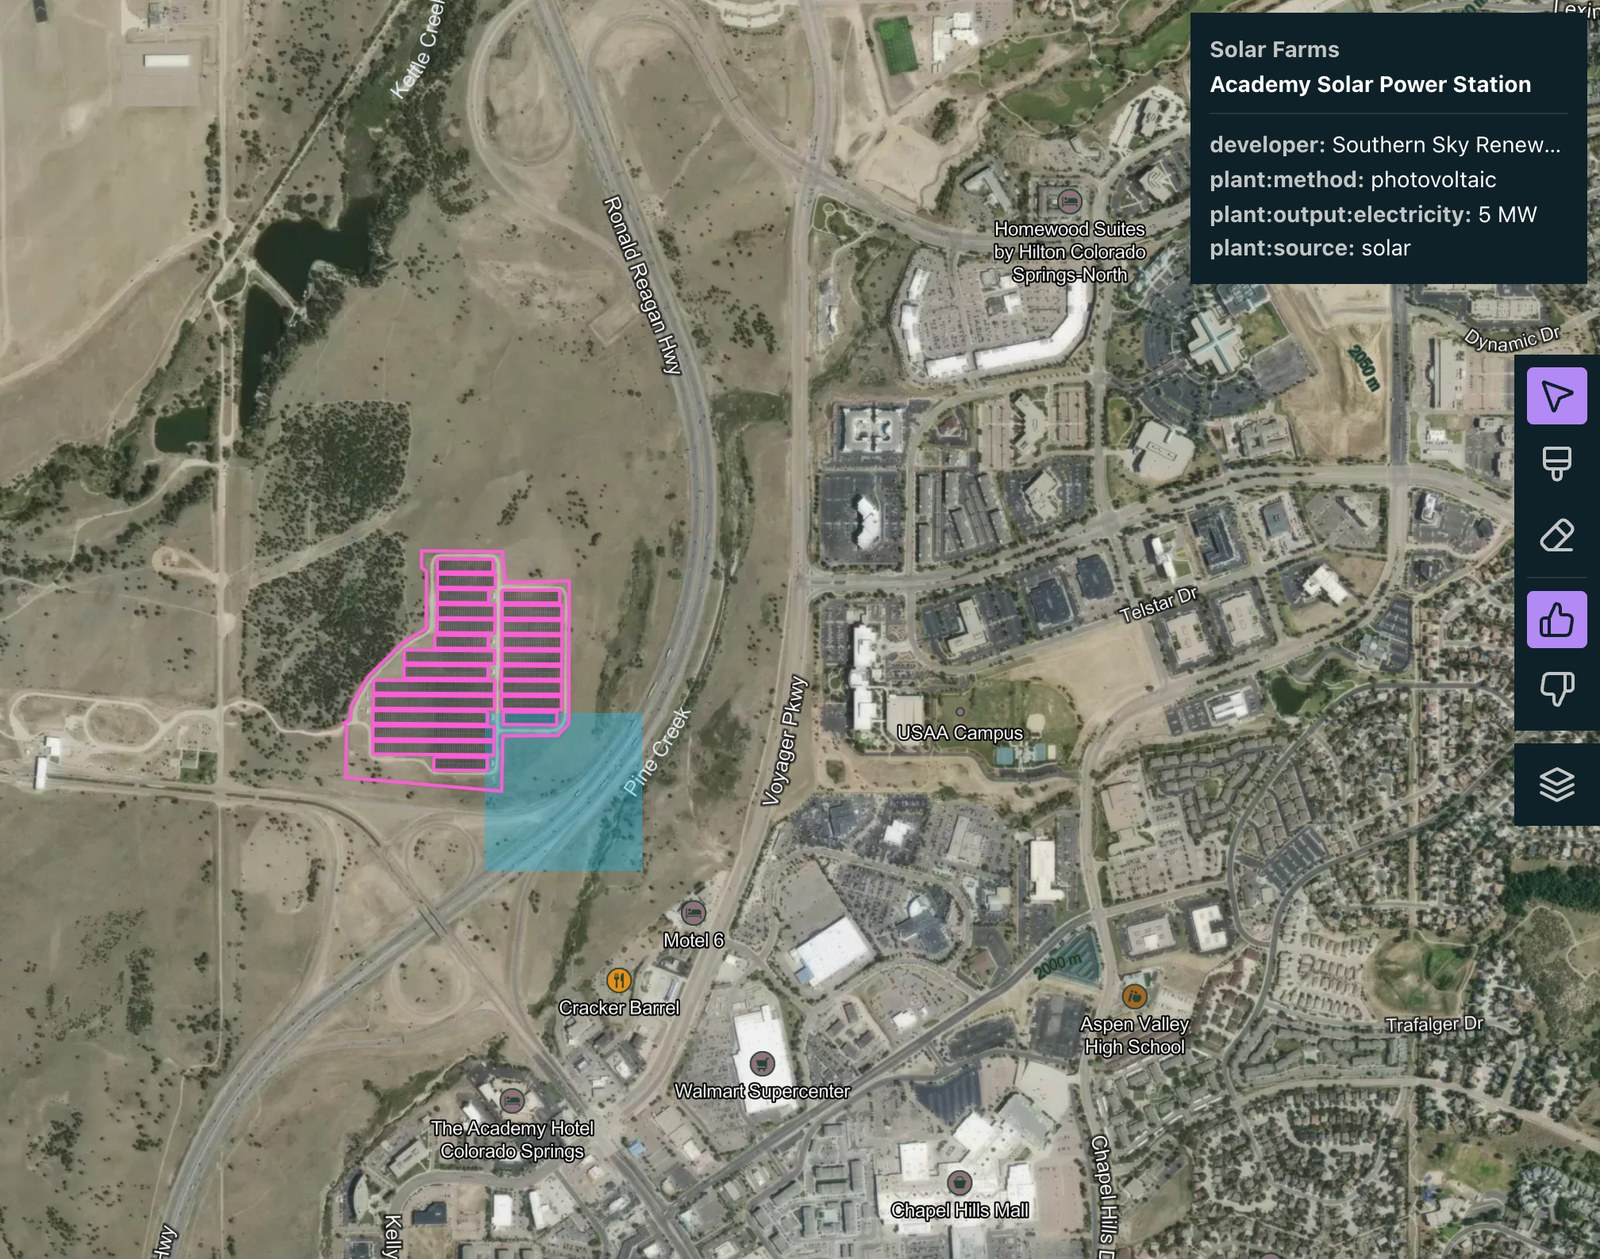
We recently launched Search for Stuff, a new way to hit the ground running in Earth Index. Describe what you’re looking for in plain language (solar farms, quarries, water treatment plants) and Earth Index builds a reference layer of known locations across your area of interest.
Every search in Earth Index starts with examples. Quick Search and Deep Search learn from the places you label, so the first step in any project is finding a few positive examples. That used to mean scanning imagery by hand or uploading your own GeoJSON file. Search for Stuff gives you a head start from open data.
It simplifies the initial step of building a reference layer that forms the basis for finding similar locations elsewhere. Instead of tracing known locations, you can now just describe what you’re looking for in plain language.
Search for Stuff uses OpenStreetMap data to create a set of features likely to match your search.
Under the hood, Search for Stuff uses a large language model to translate your request into the vocabulary of OpenStreetMap: the tags volunteer mappers apply to features all over the world to describe what they are. The model considers synonyms and regional terms, and it can search the web when a concept is unfamiliar. Because language models sometimes make things up, every tag is checked against Taginfo, the public record of how OpenStreetMap tags are actually used, and rare or invented tags are dropped. We then look for matching features inside your project area and turn the results into map tiles.
Search for Stuff wins this year’s “Best Name for a new Product” award. It perfectly encapsulates the fuzzy, describe-it-and-see nature of searching with AI.
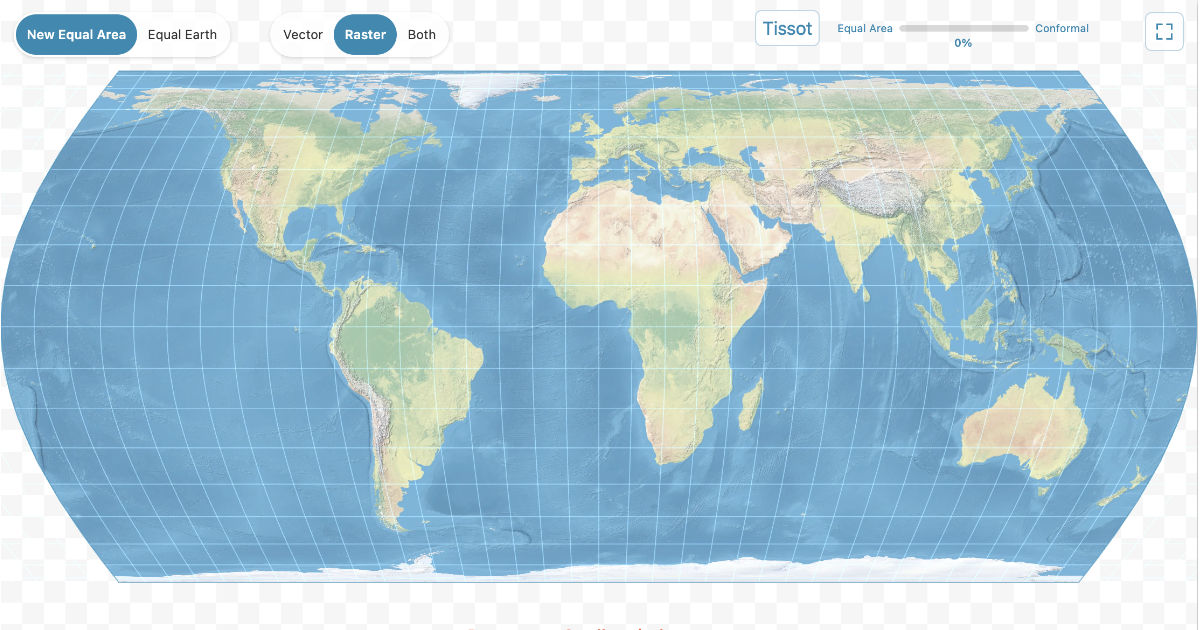
An incredible collection of 355 map projections by Tobias Jung. It comes with filtering and a neat comparison tool so you don’t have to pick dusty old Mercator when Chaise Lounge Conformal is right there.
A major reason I started using Apple Maps for day-to-day navigation a couple of years ago was that its maps just look better. They show road markings—lanes, arrows, stop lines—so I can see which lane I need before I reach a complex intersection. It’s a tiny detail, and I probably only care because I like to look at pretty maps. Most people don’t. I know my wife doesn’t.
Anyway, Mapbox now shows the road markings too, along with several other improvements to how roads are drawn.
Taya Lavrinenko, Mapbox:
Mapbox Standard now brings more detailed road surfaces, road structures, and markings directly into applications built with Mapbox Maps SDKs. At high zoom, Standard renders lane boundaries, turn arrows, pedestrian crossings and stop lines.
The additional details are off by default, so you have to enable them by setting the showHdRoads flag if you’re using the SDK or by turning on Lane Details in Mapbox Studio.
Coverage is currently limited to “71 major cities in 29 countries.” Mapbox hasn’t published which ones, though. And it looks like every city appears to be fully covered. For example, the centre of London has road markings throughout, but Kentish Town—still fairly central and by no means a suburb—is only partly covered, with the road markings stopping half-way along Kentish Town Road.
It’s complex work and you can’t just pull this level of detail from OpenStreetMap. But this looks lacklustre; a job half done. Either only roll out cities where there’s complete coverage or don’t.
deck.gl-raster, the deck.gl module for rendering Cloud-Optimised GeoTIFF and Zarr data sources, now also supports deck.gl’s GlobeView. It’s still early days: GlobeView is considered “experimental” and deck.gl-raster calls its support “preliminary”, but the examples look pretty, pretty good already.
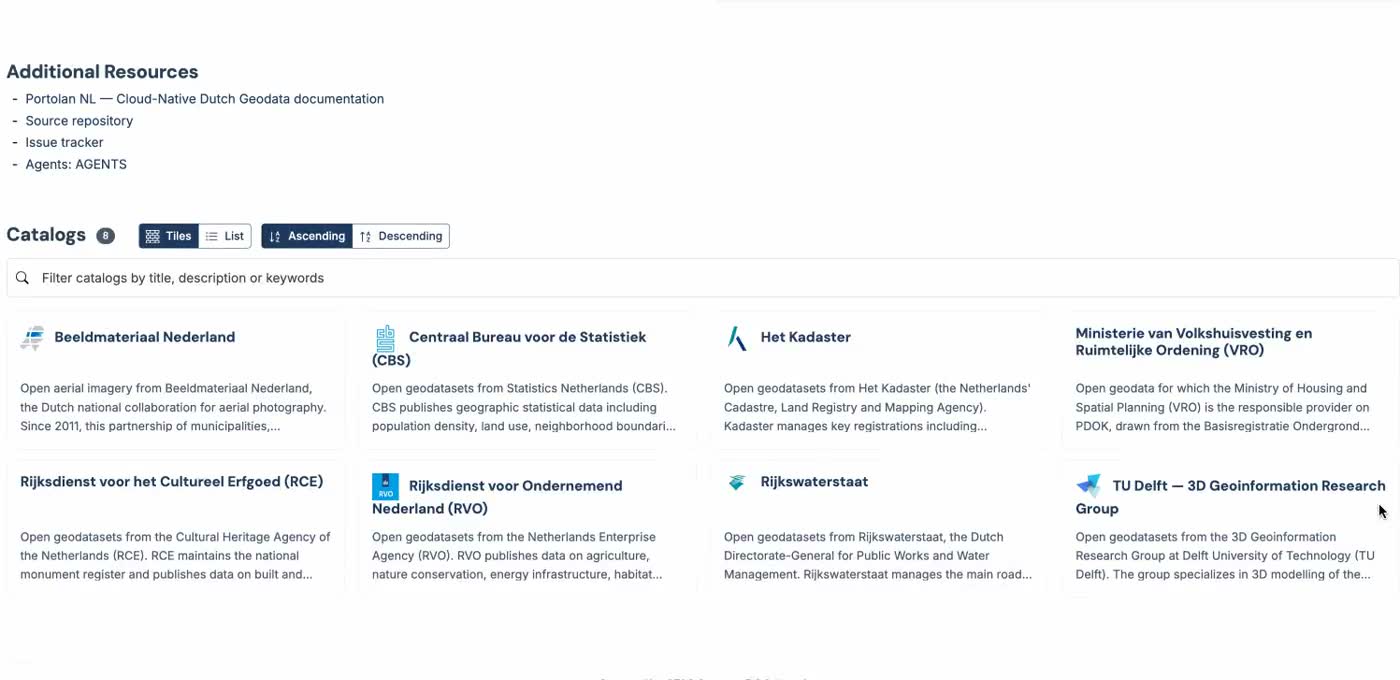
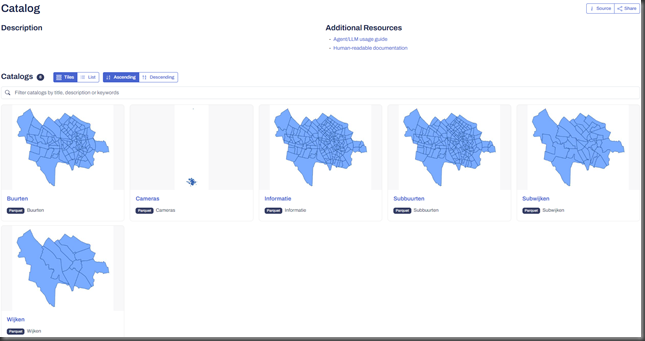
Here’s another example of how to publish a Portolan catalogue from existing data: Chris Holmes mirrored an existing catalogue of Shapefiles and published the Portolan version in just three hours, complete with custom styles and a customised Portolan browser. Unlike Bert Temme, who used the CLI, Chris used an early version of the Portolan agent skills in Claude.
The thing that strikes me most is how easy this is to do. I spent no more than 3 hours on the entire project, building both the catalog and the custom data browser. Most of it ran independently on the plane, and then I did some iterations on the results. I’d guess that doing the same project with the progress we’ve made in the last month would make it less than an hour of work to get to where I did. Yes, you need Claude or another capable agent, and it’s probably a few dollars worth of tokens if you’re paying API list rates. The agent is most of what makes this so easy, but it’s also the simplicity of the output - all the agent needs to do is format the files right, and then all the cool tooling ‘just works’.
Dana Bauer, Seth Fitzsimmons, Victor Schappert, Jennings Anderson, Roel Bollens, Tristan Diet, writing on the Overture blog:
Two weeks ago we quietly published v2.0.0 of the Overture schema to PyPI. It used to be JSON Schema, lovingly handwritten in YAML to get around some of JSON’s rough edges. Now it’s a Python library you install and import, with Pydantic models you can inspect, validate data against, build on, and extend. […]
The new Pydantic models are now the source of truth, and everything else we ship is generated from them: the JSON Schema, the PySpark validation expressions used by Overture’s internal data pipelines, and the reference documentation on this site. They can’t drift apart, because they all come from the same place.
This solves a problem that has dogged Overtures schema documentation: the data schema describes a JSON document but the data itself ships as GeoParquet.
The schema reference is still around as a website, too. Not everyone wants to install a Python library and parse its contents on the command line just to find out the name of the field that gives you a building’s floor count.
zarr-python is transitioning into an umbrella project for several Zarr-related Python packages that were previously maintained separately. Some are already integrated, including zarr-metadata, zarr-indexing and zarr-http-server; other integrations are currently underway.
Projects under the zarr-python umbrella will be released individually, so they can be used independently from the zarr Python library. Some functionality from those libraries is currently replicated in the zarr library, but work is underway to resolve that duplication by having zarr depend directly on those libraries instead.
Why are you even reading this blog if you’re not into map projections and the mathematics behind them?
Ben Joffe has you covered with an approach to creating multi-projection interactive maps that morph between equal-area and Mercator-style conformal projections based on the zoom level. We’ve had these flexible map projections for a while—MapboxGL introduced one as a commercial solution in 2022—but Joffe uses a simpler formula that includes constants derived from subjective visual tuning.
Daniel Huffman has collected use cases where generative AI tools could help with static map-making. Huffman focuses on the boring parts of cartography, the grunt work: tasks like label checking, georeferencing, extracting data from map images, or just finding data.
Daniel Huffman, somethingaboutmaps:
I think all of these examples point towards ways that genAI might make its way into some cartographic pipelines. I’m not a genAI champion, and I both respect and largely agree with people who decline to make use of it. But, I’ve also seen many folks using AI to make maps from scratch with a simple image generation prompt, and I don’t think that’s a useful example for professional mapmakers. For the cartographers that are excited to use these tools, I wanted to suggest constructive, practical directions.
Importantly, my suggested genAI uses (1) don’t significantly undercut the human creative aspect, (2) can easily be checked for errors, and (3) might actually save time and labor (if not now, probably soon).
It’s a balanced, clear-headed review of generative AI’s capabilities for a specific profession, demonstrating what works and what doesn’t.
Chris Holmes shares his personal origin story of Portolan, which is rooted in his experiences building spatial data infrastructures twenty years ago.
The early rise of AI made it even more clear to me that all the past SDI initiatives had fundamentally fallen far short of the vision to ‘enable the discovery and use of geospatial information by users and for purposes other than those it was created’ (Kuhn 2005) or to deliver ‘spatially related data from many different sources to the widest possible group of potential users at affordable costs’ (Groot & McLaughlin 2000).
[…] the example Jen Marcus (another of the people I’ve most enjoyed working with) and I would give in the early days of Fields of The World (FTW) - ‘How many fields are there in Kansas?’ If SDIs had been successful then this should be trivially easy for an LLM to answer - they sucked up all the world’s information and so of course geospatial information should be there too. But I see the lack of that information as a failure of our industry - we should have done better and actually made foundational geospatial information open and accessible for the frontier labs to gobble it up.
Astonishingly, Portolan’s solution isn’t more infrastructure, new APIs, or a fleet of MCP servers. It’s just a bunch of Markdown files, JSON documents, and a couple of skills sprinkled on top, pointing AI agents in the right direction. It’s so unbelievably simple that it scales better under today’s deluge of a thousand bots slurping up every last bit of information available on the Web. This simple design is why Portolan has such huge potential.
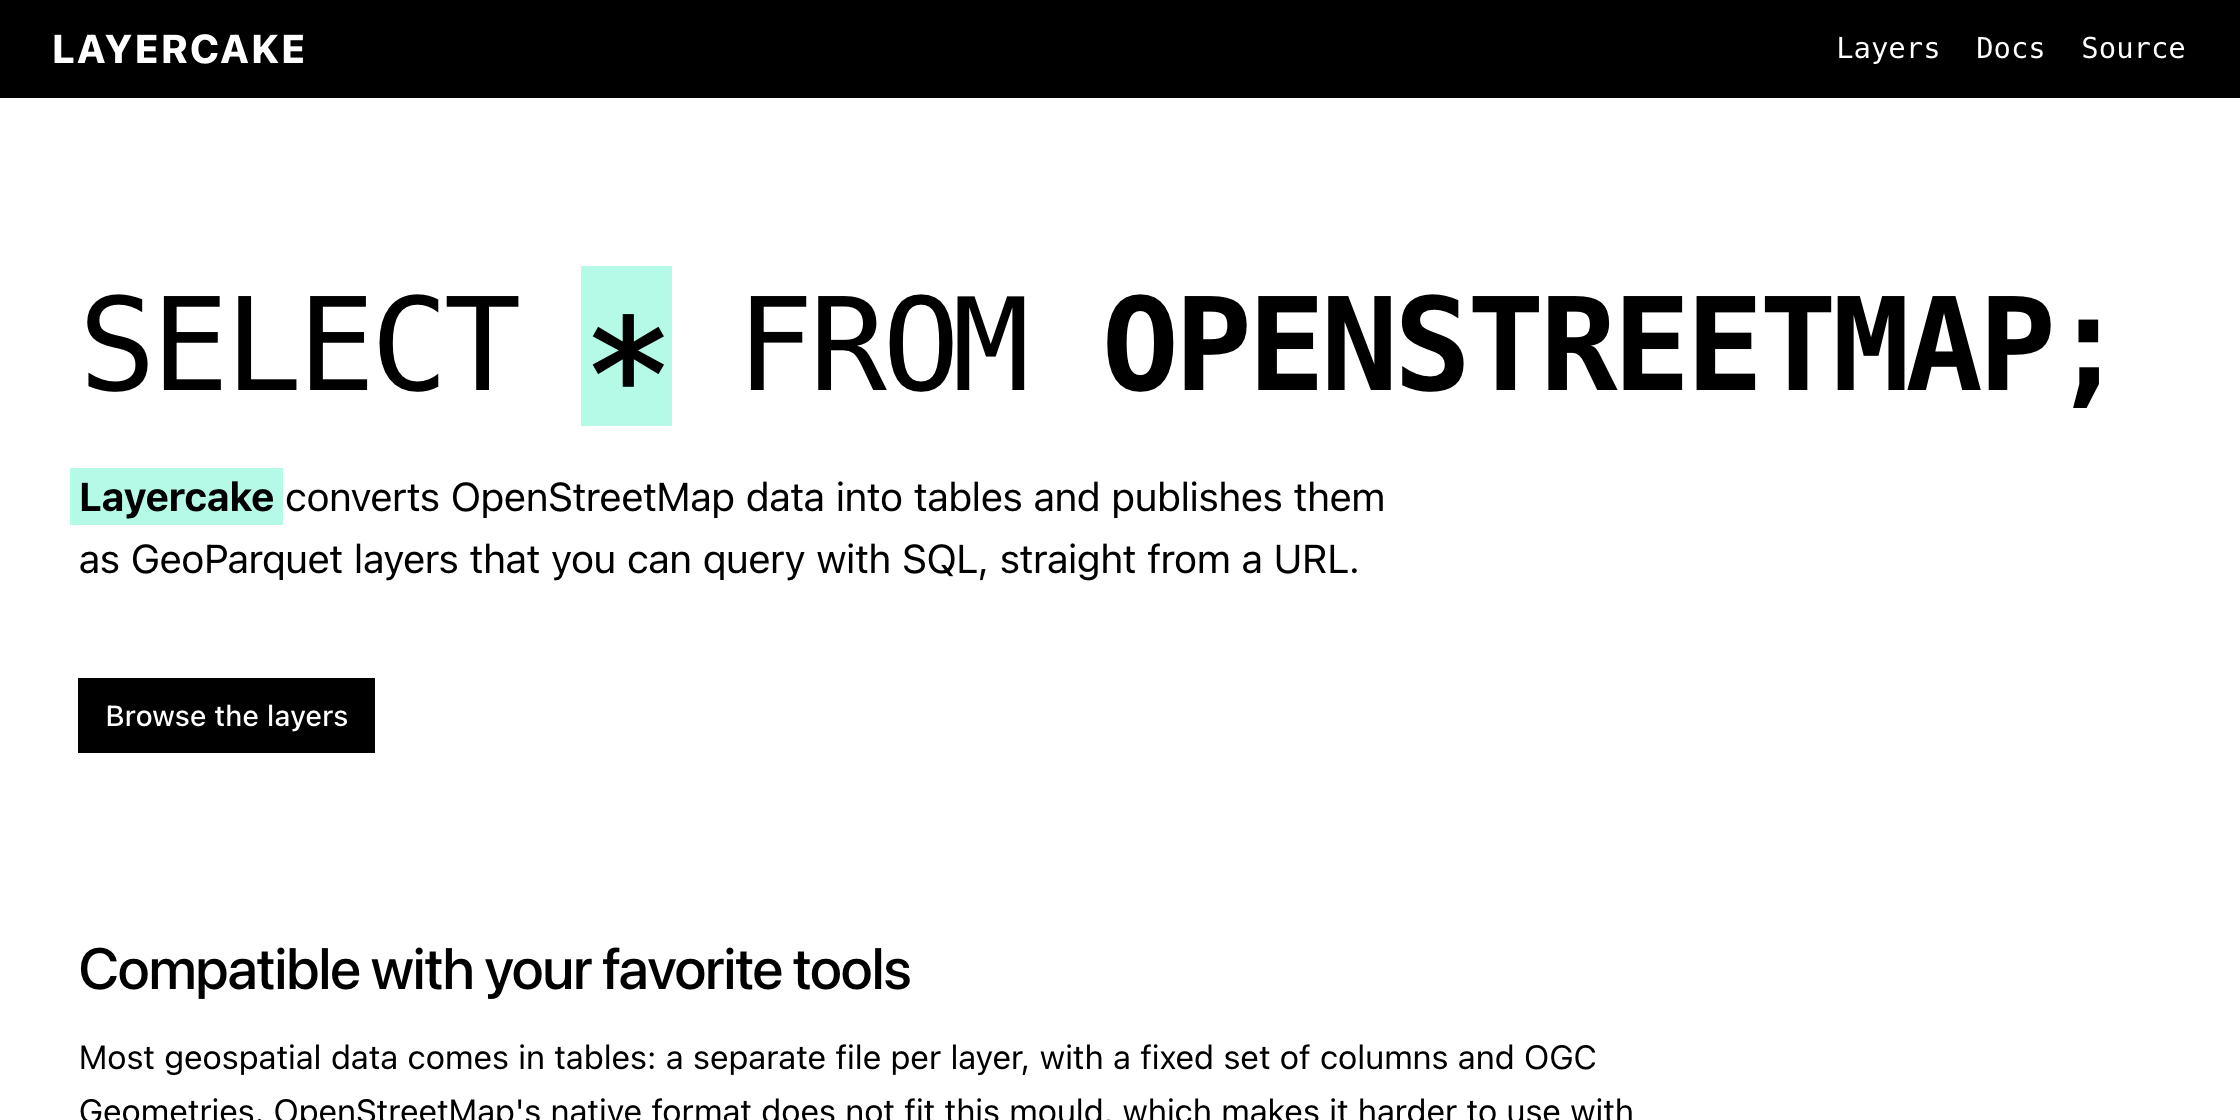
Layercake, the GeoParquet distribution of thematic data layers derived from OpenStreetMap, has a snazzy new data explorer and export tool.
Jake Low:
The new website also includes an interactive data explorer and download tool. Click “Open in viewer” on any layer and you’ll be able to fetch data for a region (by drawing a bounding box, polygon, or simply zooming to the area of interest). You can filter data by specific OSM tags, select which columns you’re interested in, and then export the data in GeoJSON, Shapefile, GeoParquet, or CSV format. All of this works directly in your browser via DuckDB (compiled to WebAssembly); there’s no backend apart from the ordinary HTTP server which hosts the Layercake GeoParquet files.
The data explorer is fast and intuitive; one of the best ways to explore OpenStreetMap data without downloading the planet file.
Google’s research team ran an A/B test on Google Maps to find out whether diverting traffic away from congestion-prone routes reduces congestion in San Francisco.
Neha Arora and Aboudy Kreidieh, Google:
In “Urban congestion relief experiments through routing-app interventions”, published in Nature Cities, we present the first large-scale, real-world study into the use of navigation platforms to improve traffic. We show that coordinating even a small fraction of trips to disperse traffic can measurably improve driving speeds and reduce emissions for the entire city.
There is a positive effect for some. People living along those roads seeing more traffic as a result of Google’s change will disagree. As with so many traffic interventions, this again solves the wrong problem. We need fewer cars on the road, full stop, not better distribution thereof. That would reduce congestion and emissions in urban areas more than diverting cars.
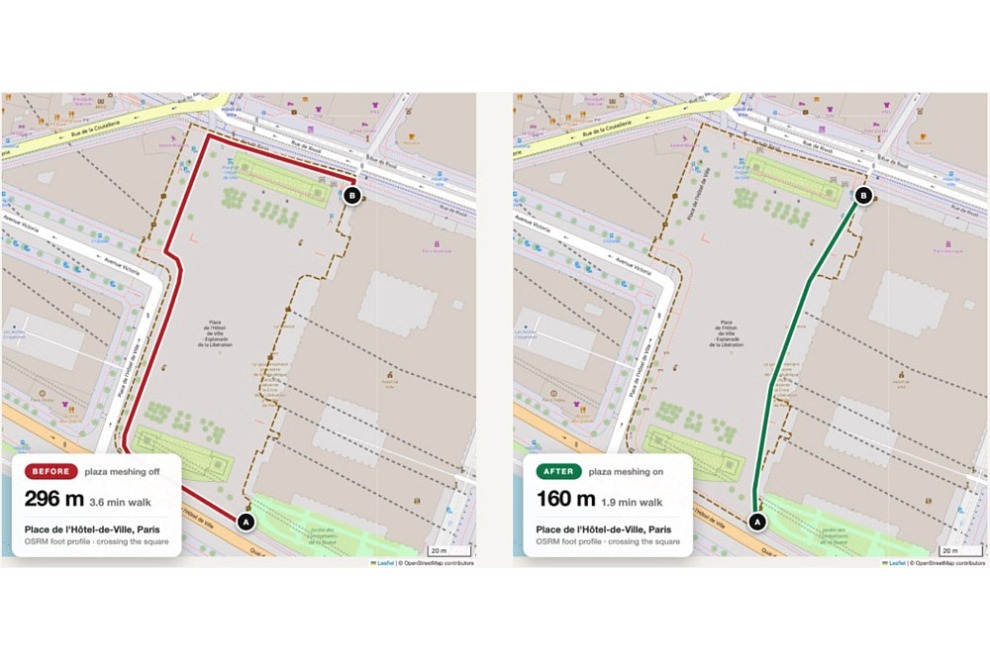
There has been an increase in attention surrounding pedestrian routing, as two prominent OpenStreetMap-based1 routing engines, OSRM and Valhalla, have started to calculate routes not just along paths, but also across walkable surfaces such as squares, pedestrian zones and station forecourts. This brings routing much closer to actual human movement. As far as I know, Google Maps does not yet offer this feature, often offering detours around the perimeter of large squares instead.
The two engines take different approaches to offer the new functionality: Valhalla generates an internal routing graph for pedestrian areas, enabling large squares or pedestrian zones to be crossed quasi-naturally, even when no individual paths are mapped. OSRM introduces a model called “Open Area Routing” (also referred to as “Plaza Routing”), which explicitly accounts for surfaces. Origins and destinations can lie inside an area and its geometry is factored directly into route and distance calculations.
I did not know about these changes; very cool to see.
Apple confirmed to 9to5Mac that the ads rollout in Maps began in the last few days. And it will continue ramping in the weeks ahead to all users.
There are two places you’ll find ads in the Maps app:
Before searching: Suggested Places in the search screen will feature an ad.
After searching: Ads will appear in search results when relevant.
Ads appear just like every other business listing, except they have a small blue badge that says ‘Ad.’ You can see examples of ads in the images above.
Before searching, I saw an ad for an HVAC contractor 12 miles away in “Suggested Places”. Knock on wood but I currently have no HVAC problems, and even if I did, I’d just call someone and have them come here. Then I waited a few minutes and looked again. This time I saw an ad for Tommy’s Express Car Wash (“Get your first month free”), 23 miles away in the middle of a suburban shopping mall. Apple Maps estimates it would take me 1 hour 8 minutes to drive there right now. I’ll get right on that.
The HVAC contractor (Heating, Ventilation, and Air Conditioning, for people like me who have to look up the acronym) is exactly the kind of business I don’t need on a map. Unless, of course, there is a showroom where I can check out the latest heat-pump models. One of my favourite pastimes.
The car wash belongs on a map. Most people will just go to one they already know, but a small number might still consult a map to find one. What I don’t understand is the economics of advertising a car wash on Apple Maps. Does this ad really convince enough people to head to that specific car wash to make the ad’s cost worthwhile? And does Apple make enough money from selling these ads to make it worth cluttering up search results?
Bert Temme put the recently released Portolan CLI through its paces and published a new data catalogue, starting with a dataset hosted an ArcGIS.
Extracting two datasets from ArcGIS, creating catalogue and PMTiles, publishing the catalogue took a total of eleven commands. That includes installing the CLI and checking its version. Publishing data in an open format doesn’t get much simpler than this.
Ian has been a member of our community from the very beginning, as an original voting member who gathered in Chicago in February 2006 to establish OSGeo. He also is a co-founder of GeoTools, the Java library that is the foundation for the Java ecosystem in OSGeo, and a Project Steering Committee (PSC) member of GeoServer. But more importantly, for decades he has been helping new users, through talks, workshops, answering questions on StackExchange, and always being a kind and jovial person. We are lucky to have him in this community.
Ian is a true veteran in the open-source geospatial world. This award is well deserved.
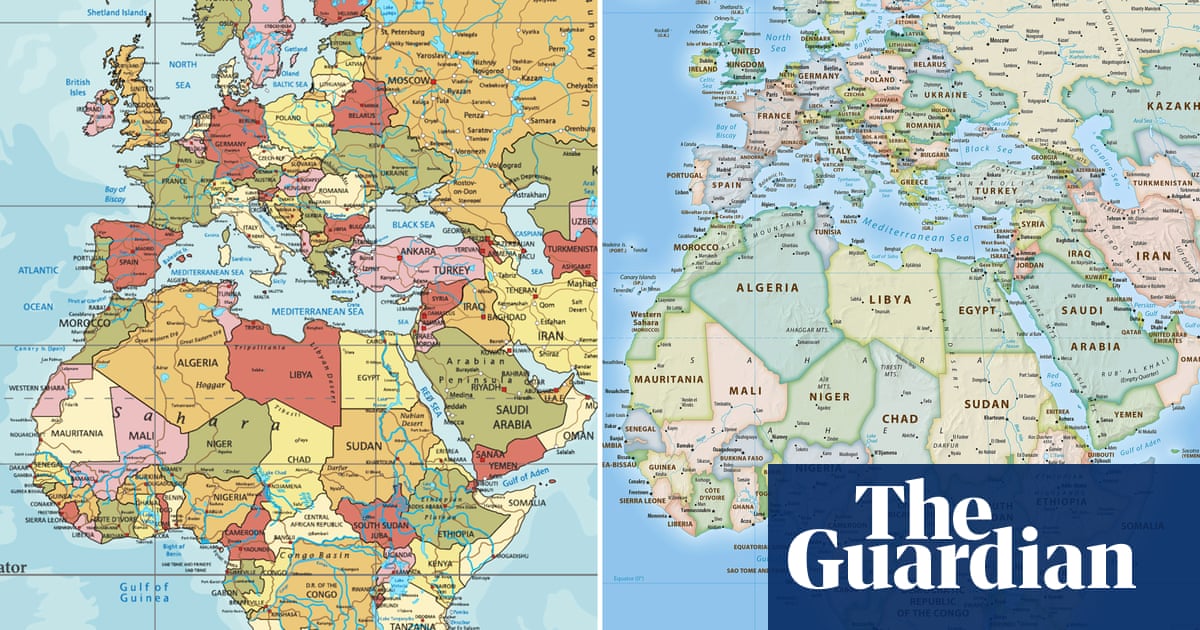
The United Nations has voted to adopt a resolution for the world to formally phase out the traditional Mercator map of the globe in favour of one that more accurately displays Africa’s size.
In a session at its headquarters in New York, the UN general assembly officially retired the 16th-century Mercator projection in favour of one based on the more accurate 2018 Equal Earth design.
At the session, 164 countries voted in favour of the resolution. Only the US voted no, with its representative saying the resolution was “superfluous”. There were six abstentions.
Queue the executive order renaming Earth to “Planet America”.
Despite recent technological advances, publishing geospatial data is still hard. It requires various tools and extensive infrastructure to prepare and host large datasets online. Questions remain: what formats should the published data use, how should the data catalogue be structured, and where should the data be hosted?
Portolan introduces strong, opinionated conventions to simplify geospatial data publishing. It builds on STAC and adds conventions to make the data discoverable for API clients, AI agents, and humans alike. It introduces tooling to create and publish catalogues alongside the data, agent skills that guide AI agents on how to use the catalogues and access cloud-native data, and a central catalogue registry.
The Portolan Specification
A Portolan catalogue is a valid STAC catalogue. It is organised into (sub-)catalogues and collections. Each catalogue or collection includes a STAC-compliant JSON document describing the data.
But Portolan reins in some of STAC’s flexibility. Catalogues can only nest other catalogues or collections. Collections themselves must not contain other catalogues or collections; only items are allowed. Titles and thumbnails are required, making it easier for humans to understand what data a catalogue offers. Each scene—if you work with satellite images—must be represented with its own item.
Where STAC is an API for client applications, Portolan adds access points for humans and agents alike. Required README.md and AGENTS.md files live alongside STAC-compliant metadata and describe the data in a human- and agent-readable way.
With Portolan, the data lives alongside its metadata in the same directory as the collection or item. The data must be provided in a cloud-native format: “GeoParquet and PMTiles for vector, COG for raster, COPC for point clouds, and Parquet for non-spatial data.” (Although point-cloud support is currently not implemented.) By leaning into cloud-native formats, running a Portolan catalogue requires little infrastructure besides a public S3-compatible object storage. Browsers access data slices via HTTP range requests without requiring intermediary APIs.
Each collection must include a way to visualise its data, either by rendering the data from source or by adding a pre-rendered visualisation, such as a PMTiles archive.
Publishing a Portolan catalogue
Besides the catalogue and data specification, the Portolan ecosystem includes a suite of tools for creating, publishing, and validating catalogues.
Command-line interface. The portolan-cli offers tools supporting the complete data-publication process: from preparing data in the right formats to generating the catalogue and publishing it to object storage. Instead of manually invoking several tools like GDAL or Tippecanoe and editing JSON documents by hand, the Portolan CLI becomes the one-stop tool for geospatial data publication.
It converts vector and raster data from a variety of formats to GeoParquet and Cloud Optimised GeoTIFF; it can even extract data from proprietary sources like CARTO and ArcGIS, or from more old-fashioned but open ones, like WFS. It generates Portolan-compliant metadata from YAML files and produces data visualisations, including thumbnails, PMTiles, and MapLibre styles. Once the catalogue is ready, you push the catalogue files to an S3-compatible storage system using the CLI.
Agent skills. If you prefer not to do much work and have AI handle your day-to-day data publishing tasks, the portolan-skills have you covered. They’re a set of agent skills that help agents execute Portolan-related tasks, such as creating and updating catalogues, generating thumbnails, or reading catalogue data.
Catalogue registry. The Portolan registry is the central entry point for finding and exploring Portolan catalogues. It currently includes twenty catalogues covering datasets across the globe. Once you have published your Portolan catalogue, you can add it to the registry by submitting the URL through the web form or opening a pull request to the registry’s repository. Humans can now find your data via the Portolan browser, a STAC-browser fork with Portolan-specific features added.
Portolan is more than a data catalogue specification. It’s a full suite for publishing geospatial data online, and a straightforward, cost-effective way to make it discoverable for humans and machines alike.
Vector tile server Martin will soon support GeoParquet data sources. It leverages DuckDB as an intermediate layer to generate tiles on the fly. Manbhav Sugla worked on the project during this year’s Google Summer of Code.
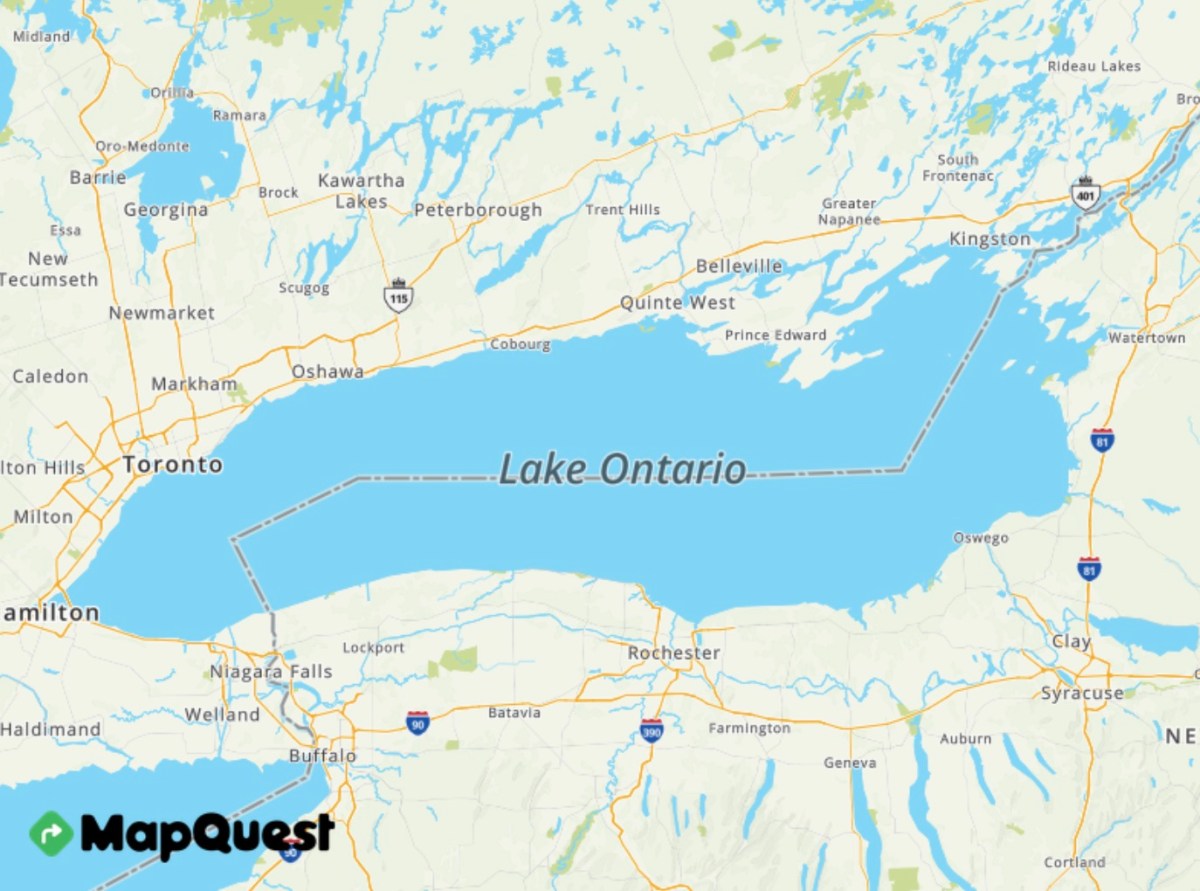
When Google renamed “Lake Ontario” to “Lake America,” MapQuest decided not to. As a result, MapQuest app downloads have soared over the last couple of days.
Sarah Perez, TechCrunch:
The “OG of online mapping,” as the company calls itself, announced on Thursday that it would not change the name of Lake Ontario on its maps to Lake America, despite Trump’s executive order directing the U.S. Department of the Interior to update the lake’s name in the U.S. geographic naming service. As a result, MapQuest’s mobile app downloads soared, sending the iOS app to the No. 4 position on the U.S. App Store’s Top Charts for apps (not including games) as of Monday morning on the U.S. east coast.
MapQuest also reached the No. 8 position overall in the U.S. App Store across both apps and games, and it became the No. 1 Navigation app in the United States.
In Canada’s App Store, the app reached No. 2 overall as of Sunday evening.
The 30-year-old company remarked that it received “hundreds of thousands” of new downloads since its decision to keep the name Lake Ontario in place, and saw its app’s usage climb to 50 times above its normal levels.
Shame that to stay on top, you have to make a product people actually want to use.
geoparquet-io is a Python command-line tool for working with GeoParquet files. Among other things, it lets you read and write GeoParquet files to and from a variety of sources (GeoJSON, GeoPackage, Flatgeobuf, and the trusty Shapefile), inspect GeoParquet files, or extract data subsets.
The latest release brings several big additions:
Support for curved geometries. Curves aren’t supported in DuckDB, which drives geometry handling under the hood, so curves are converted to lines or polygons before being stored in GeoParquet.
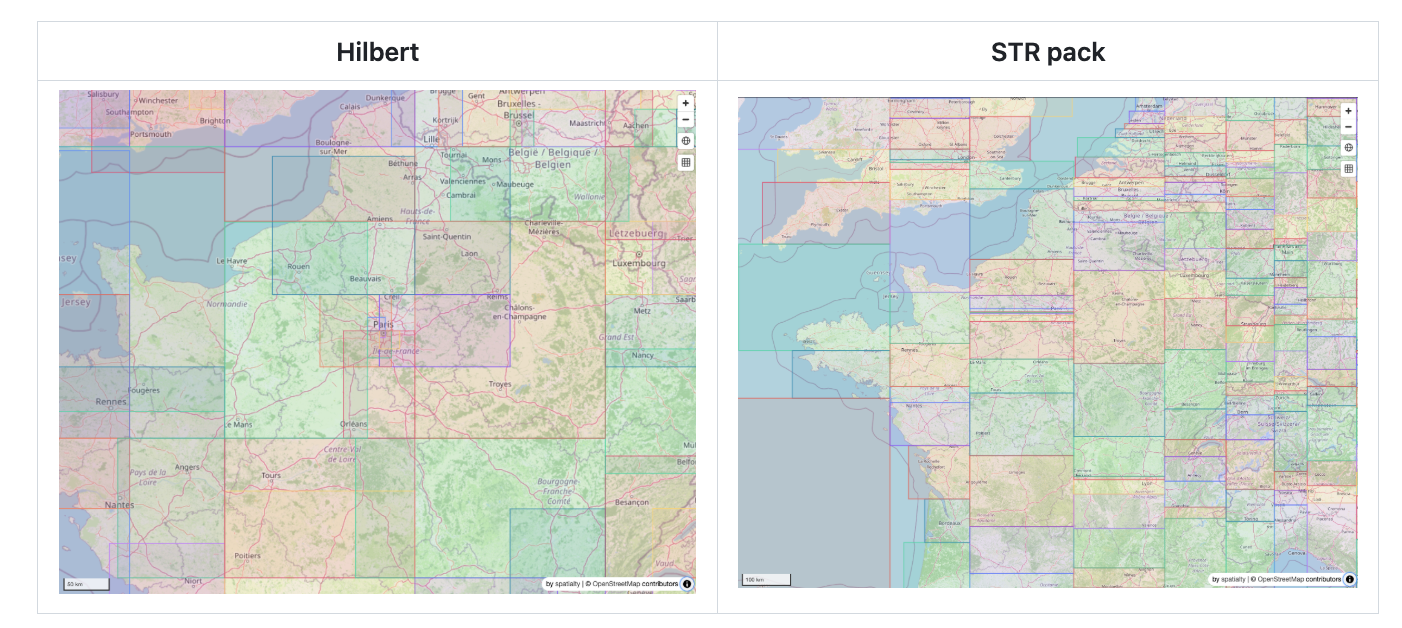
Sort Tile Recursive (STR) sorting, an alternative to Hilbert Curve sorting, which performs better “in terms of spatial locality and remote query performance.”
Aggregations over A5 and H3 grids or administrative boundaries, providing summaries of selected columns.
Many other smaller fixes and improvements include WFS support, PMTiles output, and ArcGIS error reporting.