Lat × Long
Kiri Carini and Martha Morrisey’s primer on geospatial embeddings is, hands down, the best I’ve encountered. It covers what embeddings are, how they are produced and what they are used for.
Instead of relying only on human-defined categories or measurements, foundation models learn representations directly from Earth observation data. The outputs of those systems — embeddings — are becoming an increasingly important building block for retrieval, similarity search, clustering, and other emerging geospatial AI workflows.
If you’ve spent the last year hearing terms like “GeoFM,” “foundation model,” or “embedding” without a clear mental model for how they connect together, this post is for you.
There is also a poster that fits nicely in your home office and a mini zine for your coffee table, so you get to impress your colleagues and friends as well.
With Portolan, stac-zap and stac-fastapi-collection-discovery we’ve recently covered various approaches to facilitate searching across several STACT catalogues. Portolan and stac-zap provide AI-driven search against a registry, whereas stac-fastapi-collection-discovery implements a STAC-compliant search API on top of a curated index of data sources.
SuperSTAC is the latest addition to this space, providing a unified interface to search against a custom compiled index of STAC catalogues.
Emmanuel Jolaiya Ayodele:
SuperSTAC is a high availability layer for applications that depend on STAC catalogs. It lets you register multiple catalogs and search them through one interface, while providing the building blocks for handling catalog availability and provider differences.
The idea is simple: Many catalogs, One search.
Implemented in Rust, SuperSTAC comes with a Python API to build custom applications or Jupyther notebooks, and a command-line interface. And it adds some useful features that its predecessors lack: aliases and local caching.
Aliases are for people who don’t remember what name a specific catalogue uses for the blue band (i.e., everyone). Specify aliases for collection and asset names and use them to run a search. SuperSTAC translates your aliases into each catalogue’s own names before sending the search, then maps them back to your aliases in the results
SuperSTAC can also cache results locally in GeoParquet. This is particularly handy when repeated queries against a catalogue hit rate limits, or when you want to work on a plane. And cached results also come back much faster, since there’s no network round trip.
SuperSTAC looks like the most complete solution for multi-catalogues STAC search that is not AI driven. It’s not just a proof of concept, it’s a library that you can use today.
Eugene Alvin Villar writing for the OpenStreetMap Blog:
Maptober is here! Starting today, the OpenStreetMap Foundation’s Local Chapters and Communities Working Group invites mappers everywhere to take part in the 31 Day OSM Challenge. Inspired by the #30DayMapChallenge that happens every November, this new challenge gives you a daily theme to improve OpenStreetMap, from adding trees or improving woods on Day 1 to benches, bridges, railways, healthcare, and more. Just complete the day’s task, tag your changesets with #31DayOSMChallenge and #Maptober hashtags, and share your edits on social media if you like.
There’s no pressure to map every day and you can complete the challenge at your own pace. There is no prize beyond knowing you’ve contributed to the world’s best open map. This is a great way to sharpen your skills, try new tools, and learn how to map different kinds of features. Just keep to OSM’s good practices rather than mapping only to tick a box.
Check out the full list of daily themes at the OSM Wiki and start mapping!
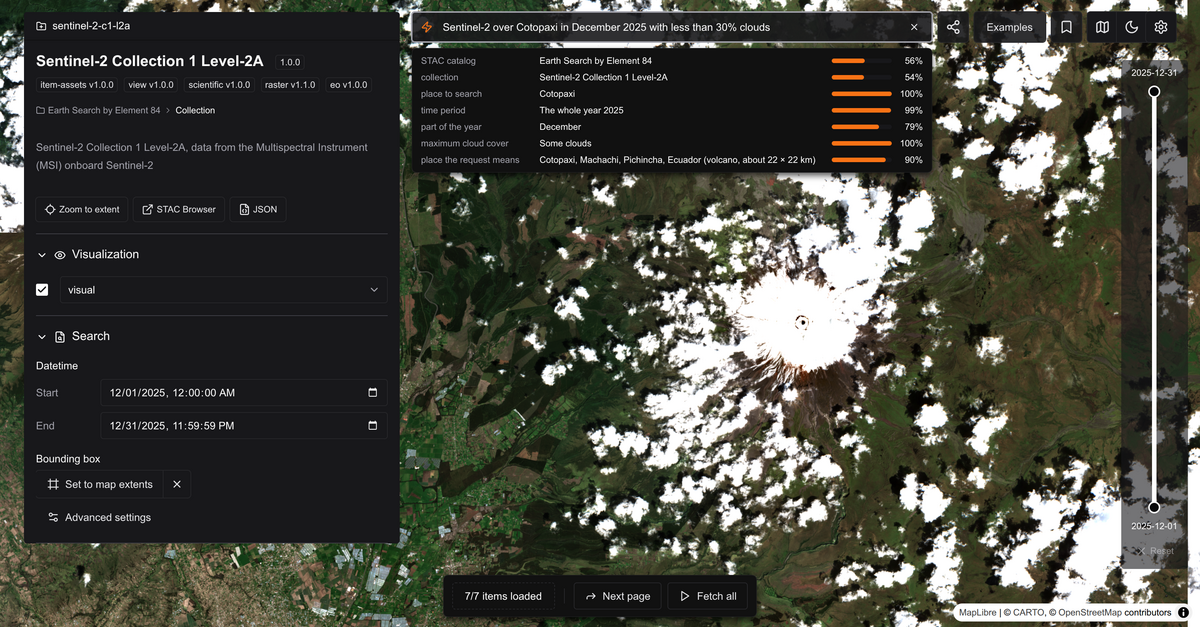
Cool new prototype from Development Seed: stac-zap builds on top of stac-map and integrates free-text search across STAC catalogues. Describe the data you need, get results.
Daniel Wiesmann, writing on LinkedIn:
You type one request in the search bar, and Jev picks the catalog and the collection, finds the place in your request, and sets the dates and the cloud cover. Jev does not write text: it only selects from options that exist, such as real catalogs, collections and places, so every search is a valid STAC query. The answers update the app state, and stac-map shows the result.
Jev is an interesting choice for translating the search request into a structured query. Unlike general-purpose LLMs, Jev works from pre-specified output types, so it always returns results in a predictable format, which makes it a better fit for many automation tasks
Turning fuzzy requests into tangible results is one of the better uses of AI. People often don’t know exactly what they’re looking for, or where to find it, especially when the data is spread across several catalogues. Right now, this still needs a well curated list of sources like STAC Index, which stac-zap uses, or the Portolan registry. Jev can only pick from catalogues it knows. AI makes searching easier but the results are only as good as the source data.
Candice Julka, CARTO:
Ubilabs is now CARTO’s exclusive partner and reseller for the DACH region, bringing CARTO’s Agentic GIS platform to organizations in Germany, Austria, and Switzerland. Ubilabs brings 20 years of geodata project experience and will help customers identify use cases, set up technical foundations, and support implementation, with analysis running inside each customer’s own cloud data warehouse.
The announcement is part of a broader push by CARTO to expand internationally through regional partners, following recent exclusive partnerships in Mexico and Argentina, Chile, Uruguay and Paraguay.
The partnership could open new opportunities for CARTO among public-sector clients in Germany, Switzerland and Austria that require German-language support and a contract with a local entity.
Earth Genome has added a new AI-driven feature for creating reference layers in Earth Index, a similarity-search application allowing conservationists to identify locations of environmental harm.
Andrew Milligan, Earth Genome:
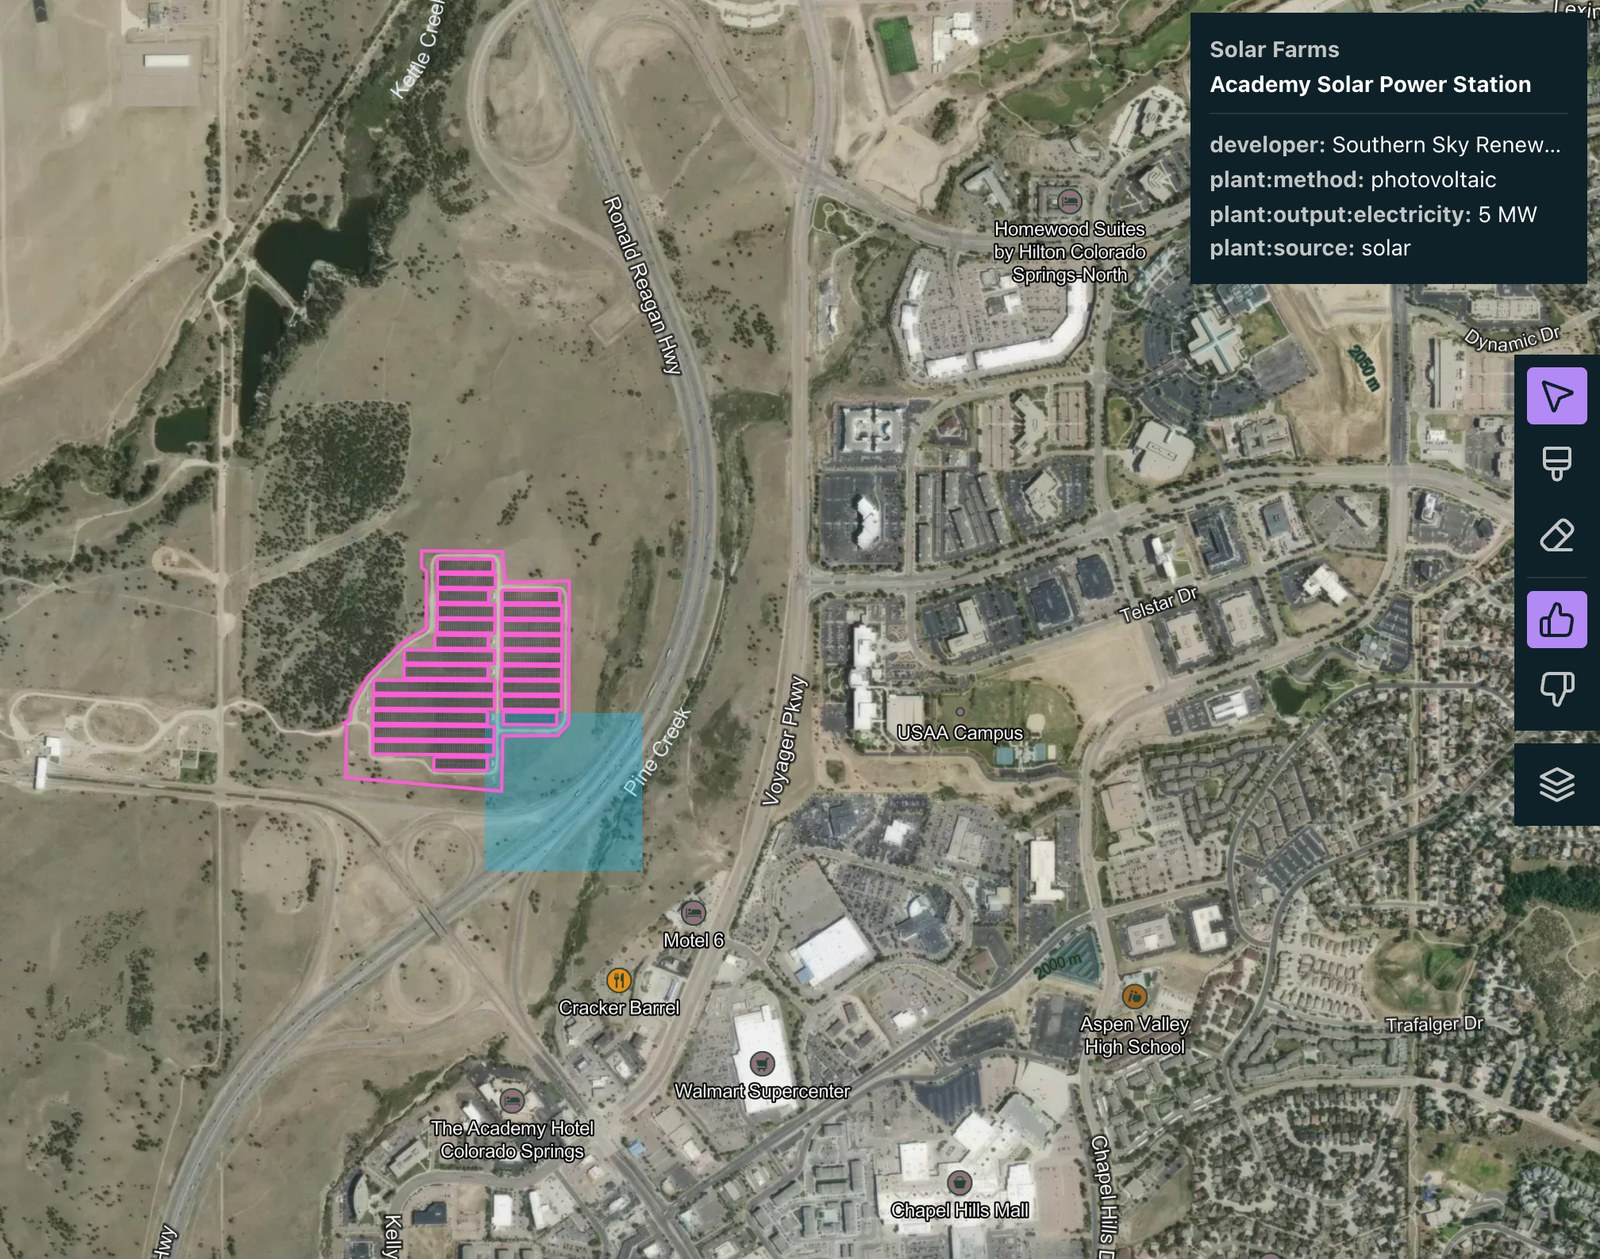
We recently launched Search for Stuff, a new way to hit the ground running in Earth Index. Describe what you’re looking for in plain language (solar farms, quarries, water treatment plants) and Earth Index builds a reference layer of known locations across your area of interest.
Every search in Earth Index starts with examples. Quick Search and Deep Search learn from the places you label, so the first step in any project is finding a few positive examples. That used to mean scanning imagery by hand or uploading your own GeoJSON file. Search for Stuff gives you a head start from open data.
It simplifies the initial step of building a reference layer that forms the basis for finding similar locations elsewhere. Instead of tracing known locations, you can now just describe what you’re looking for in plain language.
Search for Stuff uses OpenStreetMap data to create a set of features likely to match your search.
Under the hood, Search for Stuff uses a large language model to translate your request into the vocabulary of OpenStreetMap: the tags volunteer mappers apply to features all over the world to describe what they are. The model considers synonyms and regional terms, and it can search the web when a concept is unfamiliar. Because language models sometimes make things up, every tag is checked against Taginfo, the public record of how OpenStreetMap tags are actually used, and rare or invented tags are dropped. We then look for matching features inside your project area and turn the results into map tiles.
Search for Stuff wins this year’s “Best Name for a new Product” award. It perfectly encapsulates the fuzzy, describe-it-and-see nature of searching with AI.
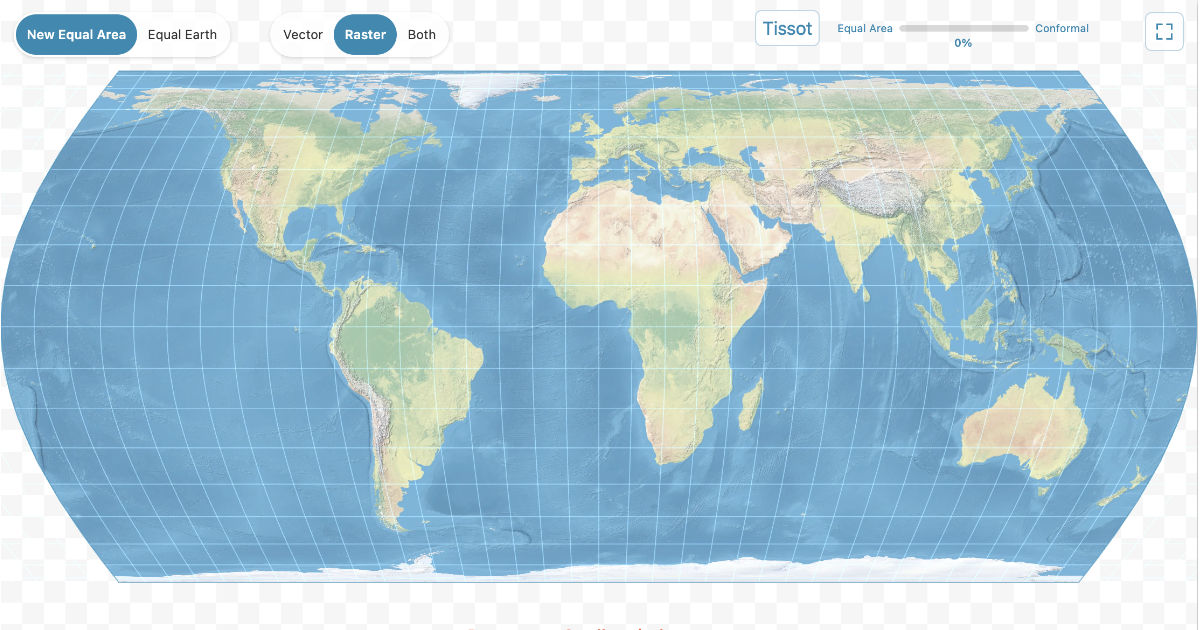
An incredible collection of 355 map projections by Tobias Jung. It comes with filtering and a neat comparison tool so you don’t have to pick dusty old Mercator when Chaise Lounge Conformal is right there.
A major reason I started using Apple Maps for day-to-day navigation a couple of years ago was that its maps just look better. They show road markings—lanes, arrows, stop lines—so I can see which lane I need before I reach a complex intersection. It’s a tiny detail, and I probably only care because I like to look at pretty maps. Most people don’t. I know my wife doesn’t.
Anyway, Mapbox now shows the road markings too, along with several other improvements to how roads are drawn.
Taya Lavrinenko, Mapbox:
Mapbox Standard now brings more detailed road surfaces, road structures, and markings directly into applications built with Mapbox Maps SDKs. At high zoom, Standard renders lane boundaries, turn arrows, pedestrian crossings and stop lines.
The additional details are off by default, so you have to enable them by setting the showHdRoads flag if you’re using the SDK or by turning on Lane Details in Mapbox Studio.
Coverage is currently limited to “71 major cities in 29 countries.” Mapbox hasn’t published which ones, though. And it looks like every city appears to be fully covered. For example, the centre of London has road markings throughout, but Kentish Town—still fairly central and by no means a suburb—is only partly covered, with the road markings stopping half-way along Kentish Town Road.
It’s complex work and you can’t just pull this level of detail from OpenStreetMap. But this looks lacklustre; a job half done. Either only roll out cities where there’s complete coverage or don’t.
deck.gl-raster, the deck.gl module for rendering Cloud-Optimised GeoTIFF and Zarr data sources, now also supports deck.gl’s GlobeView. It’s still early days: GlobeView is considered “experimental” and deck.gl-raster calls its support “preliminary”, but the examples look pretty, pretty good already.
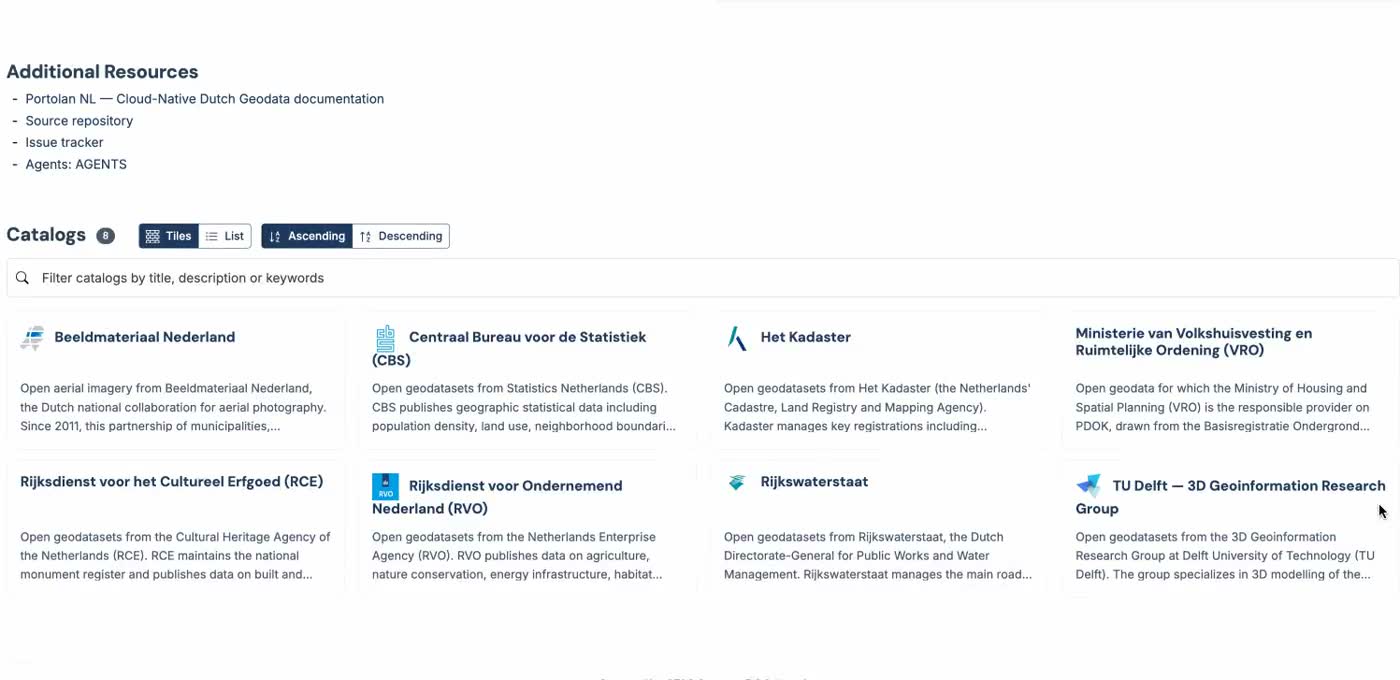
Here’s another example of how to publish a Portolan catalogue from existing data: Chris Holmes mirrored an existing catalogue of Shapefiles and published the Portolan version in just three hours, complete with custom styles and a customised Portolan browser. Unlike Bert Temme, who used the CLI, Chris used an early version of the Portolan agent skills in Claude.
The thing that strikes me most is how easy this is to do. I spent no more than 3 hours on the entire project, building both the catalog and the custom data browser. Most of it ran independently on the plane, and then I did some iterations on the results. I’d guess that doing the same project with the progress we’ve made in the last month would make it less than an hour of work to get to where I did. Yes, you need Claude or another capable agent, and it’s probably a few dollars worth of tokens if you’re paying API list rates. The agent is most of what makes this so easy, but it’s also the simplicity of the output - all the agent needs to do is format the files right, and then all the cool tooling ‘just works’.
Just three hours.
Dana Bauer, Seth Fitzsimmons, Victor Schappert, Jennings Anderson, Roel Bollens, Tristan Diet, writing on the Overture blog:
Two weeks ago we quietly published v2.0.0 of the Overture schema to PyPI. It used to be JSON Schema, lovingly handwritten in YAML to get around some of JSON’s rough edges. Now it’s a Python library you install and import, with Pydantic models you can inspect, validate data against, build on, and extend. […]
The new Pydantic models are now the source of truth, and everything else we ship is generated from them: the JSON Schema, the PySpark validation expressions used by Overture’s internal data pipelines, and the reference documentation on this site. They can’t drift apart, because they all come from the same place.
This solves a problem that has dogged Overtures schema documentation: the data schema describes a JSON document but the data itself ships as GeoParquet.
The schema reference is still around as a website, too. Not everyone wants to install a Python library and parse its contents on the command line just to find out the name of the field that gives you a building’s floor count.
zarr-python is transitioning into an umbrella project for several Zarr-related Python packages that were previously maintained separately. Some are already integrated, including zarr-metadata, zarr-indexing and zarr-http-server; other integrations are currently underway.
Projects under the zarr-python umbrella will be released individually, so they can be used independently from the zarr Python library. Some functionality from those libraries is currently replicated in the zarr library, but work is underway to resolve that duplication by having zarr depend directly on those libraries instead.
Why are you even reading this blog if you’re not into map projections and the mathematics behind them?
Ben Joffe has you covered with an approach to creating multi-projection interactive maps that morph between equal-area and Mercator-style conformal projections based on the zoom level. We’ve had these flexible map projections for a while—MapboxGL introduced one as a commercial solution in 2022—but Joffe uses a simpler formula that includes constants derived from subjective visual tuning.
Daniel Huffman has collected use cases where generative AI tools could help with static map-making. Huffman focuses on the boring parts of cartography, the grunt work: tasks like label checking, georeferencing, extracting data from map images, or just finding data.
Daniel Huffman, somethingaboutmaps:
I think all of these examples point towards ways that genAI might make its way into some cartographic pipelines. I’m not a genAI champion, and I both respect and largely agree with people who decline to make use of it. But, I’ve also seen many folks using AI to make maps from scratch with a simple image generation prompt, and I don’t think that’s a useful example for professional mapmakers. For the cartographers that are excited to use these tools, I wanted to suggest constructive, practical directions.
Importantly, my suggested genAI uses (1) don’t significantly undercut the human creative aspect, (2) can easily be checked for errors, and (3) might actually save time and labor (if not now, probably soon).
It’s a balanced, clear-headed review of generative AI’s capabilities for a specific profession, demonstrating what works and what doesn’t.
Chris Holmes shares his personal origin story of Portolan, which is rooted in his experiences building spatial data infrastructures twenty years ago.
The early rise of AI made it even more clear to me that all the past SDI initiatives had fundamentally fallen far short of the vision to ‘enable the discovery and use of geospatial information by users and for purposes other than those it was created’ (Kuhn 2005) or to deliver ‘spatially related data from many different sources to the widest possible group of potential users at affordable costs’ (Groot & McLaughlin 2000).
[…] the example Jen Marcus (another of the people I’ve most enjoyed working with) and I would give in the early days of Fields of The World (FTW) - ‘How many fields are there in Kansas?’ If SDIs had been successful then this should be trivially easy for an LLM to answer - they sucked up all the world’s information and so of course geospatial information should be there too. But I see the lack of that information as a failure of our industry - we should have done better and actually made foundational geospatial information open and accessible for the frontier labs to gobble it up.
Astonishingly, Portolan’s solution isn’t more infrastructure, new APIs, or a fleet of MCP servers. It’s just a bunch of Markdown files, JSON documents, and a couple of skills sprinkled on top, pointing AI agents in the right direction. It’s so unbelievably simple that it scales better under today’s deluge of a thousand bots slurping up every last bit of information available on the Web. This simple design is why Portolan has such huge potential.
You'll find older posts in the
archives.